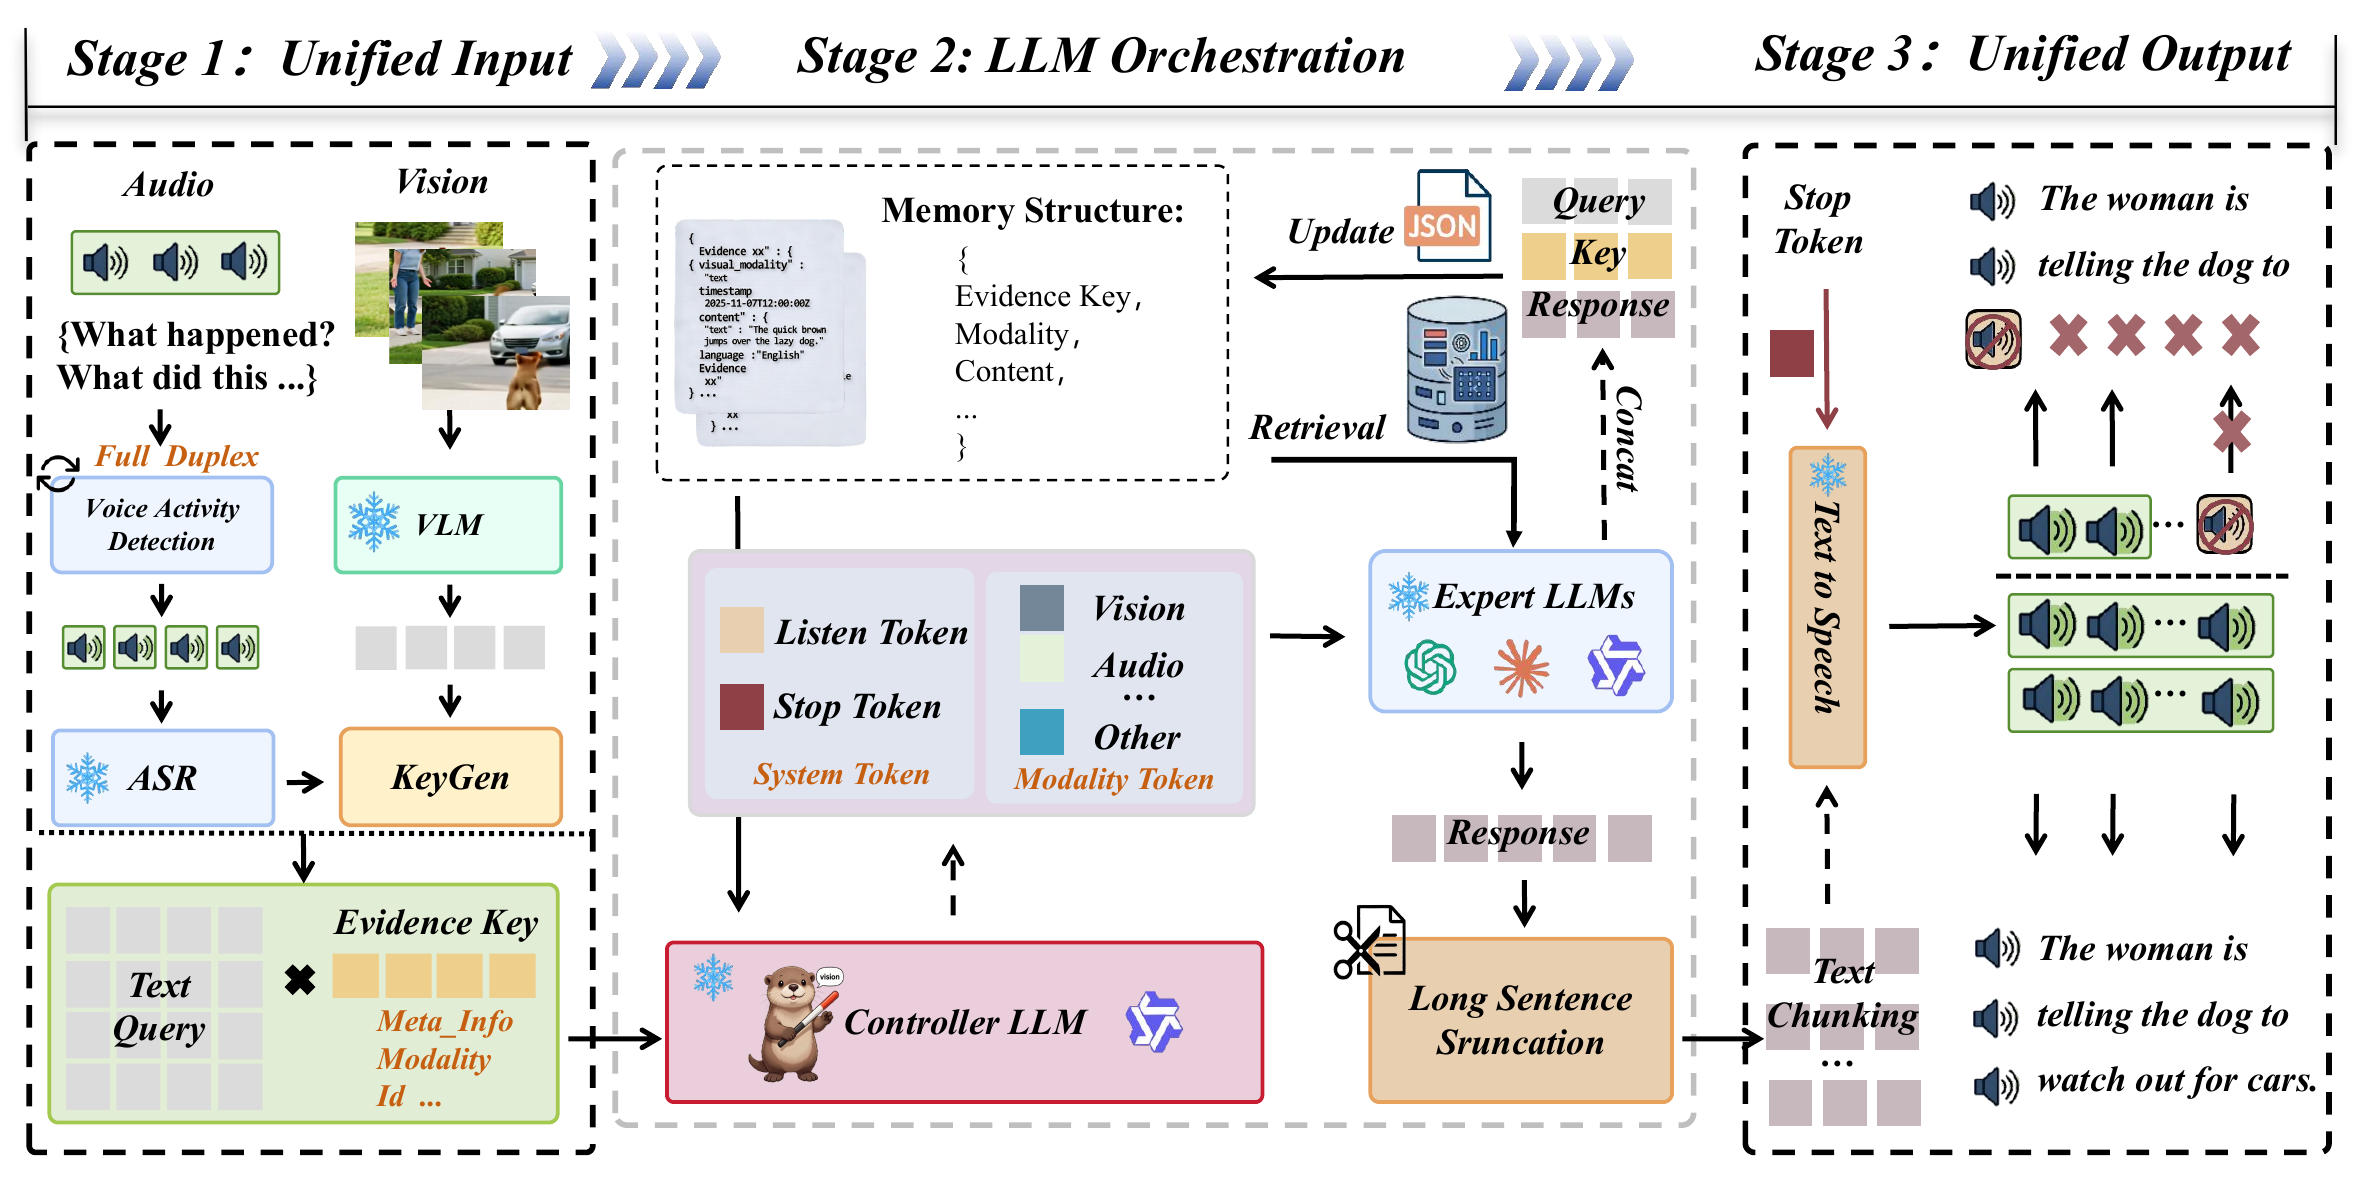
Training-Free Multimodal Large Language Model Orchestration
A language-model controller coordinates modality experts, shared cross-modal memory, and full-duplex streaming interaction without additional integration training.
I am a master's student in Artificial Intelligence at Xiamen University, working with Prof. Xiawu Zheng in the MAC Lab. I also conduct research on pre-training and post-training at a leading AI startup.
My research interests lie in omni-modal modeling and full-duplex human–AI interaction. I focus on real-time multimodal understanding, cross-modal context and memory, and the evaluation of interactive models.
Our group at Xiamen University, led by Prof. Xiawu Zheng, welcomes students interested in multimodal models and agents, automated machine learning, model compression, and efficient deployment. Visit Prof. Zheng's homepage to learn about our research, recent work, and group members.
To apply, please send your CV to zhengxiawu@xmu.edu.cn and cc teery@xmumac.com and maqingchuan@xmumac.com, along with a brief introduction to your research interests and relevant experience.
Full list: publication archive · Google Scholar
A language-model controller coordinates modality experts, shared cross-modal memory, and full-duplex streaming interaction without additional integration training.
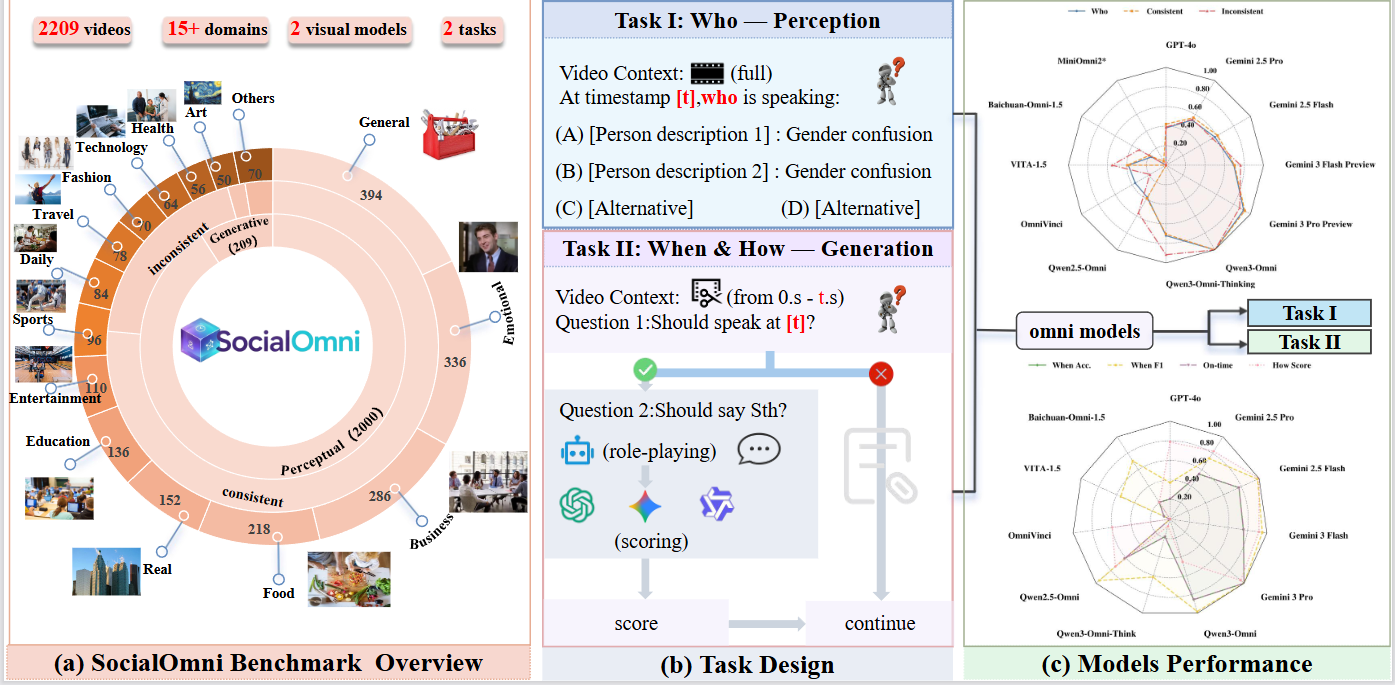
An offline benchmark separating speaker identification, turn-entry decisions, and response generation, with 2,000 perception items and 200 interaction-generation items.
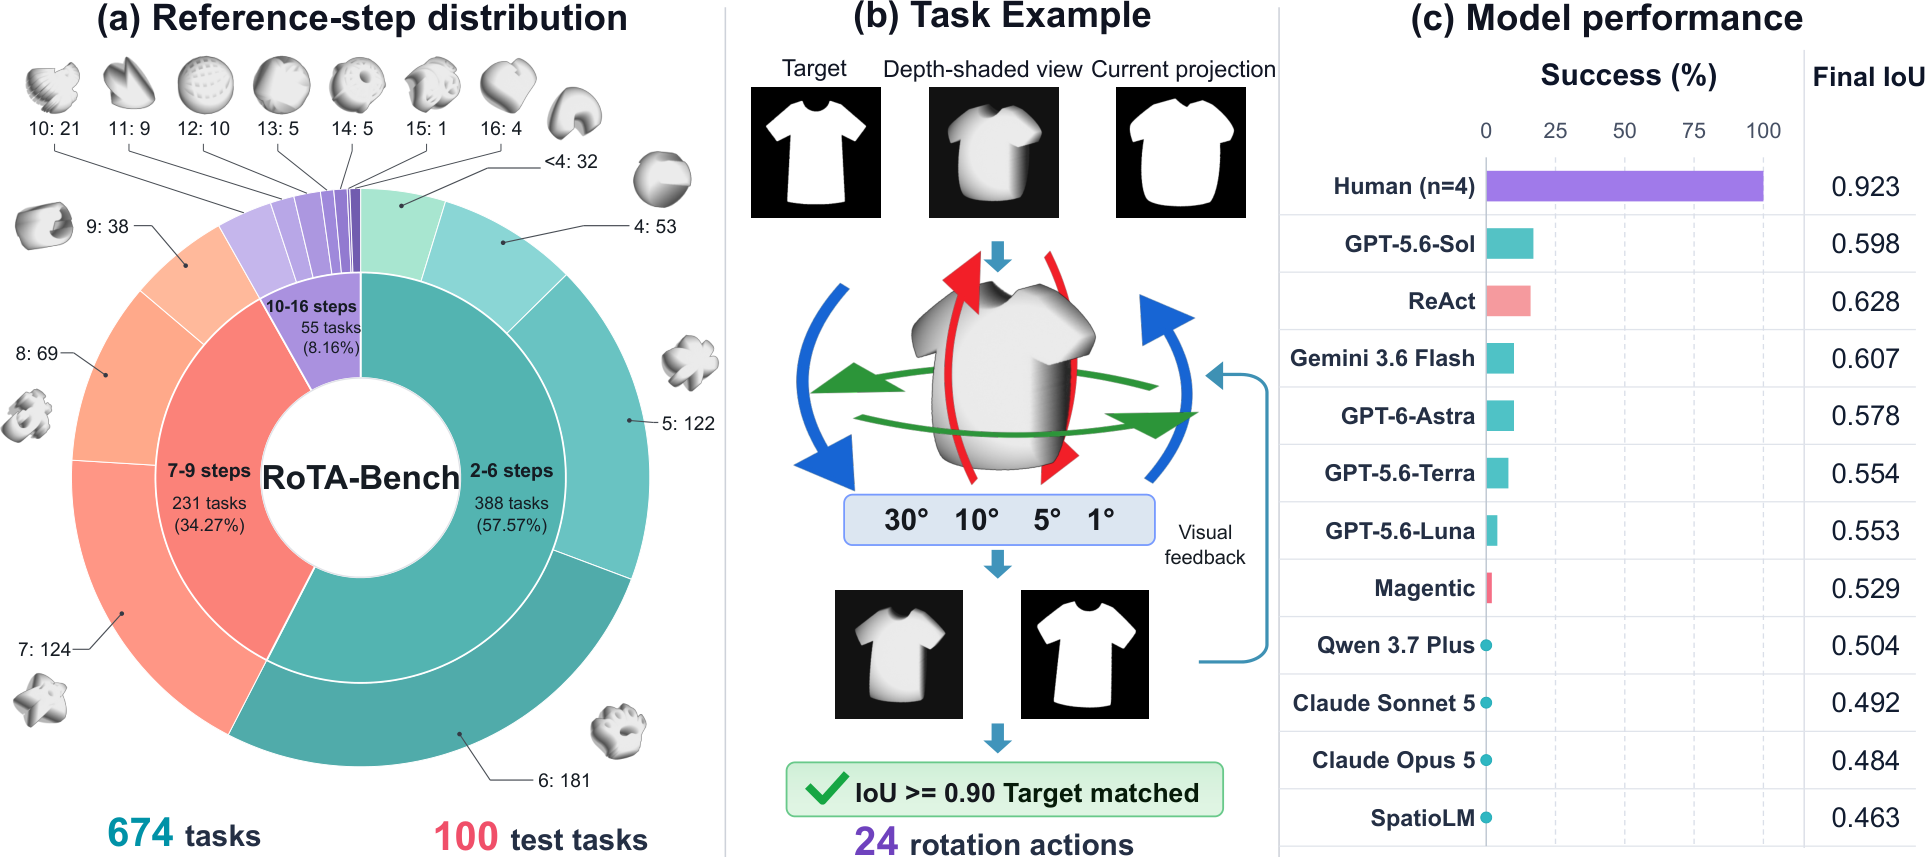
A benchmark of interactive 3D spatial reasoning: models use visual feedback to rotate objects until their projections match target silhouettes, across 674 tasks and a fixed 100-task test set.
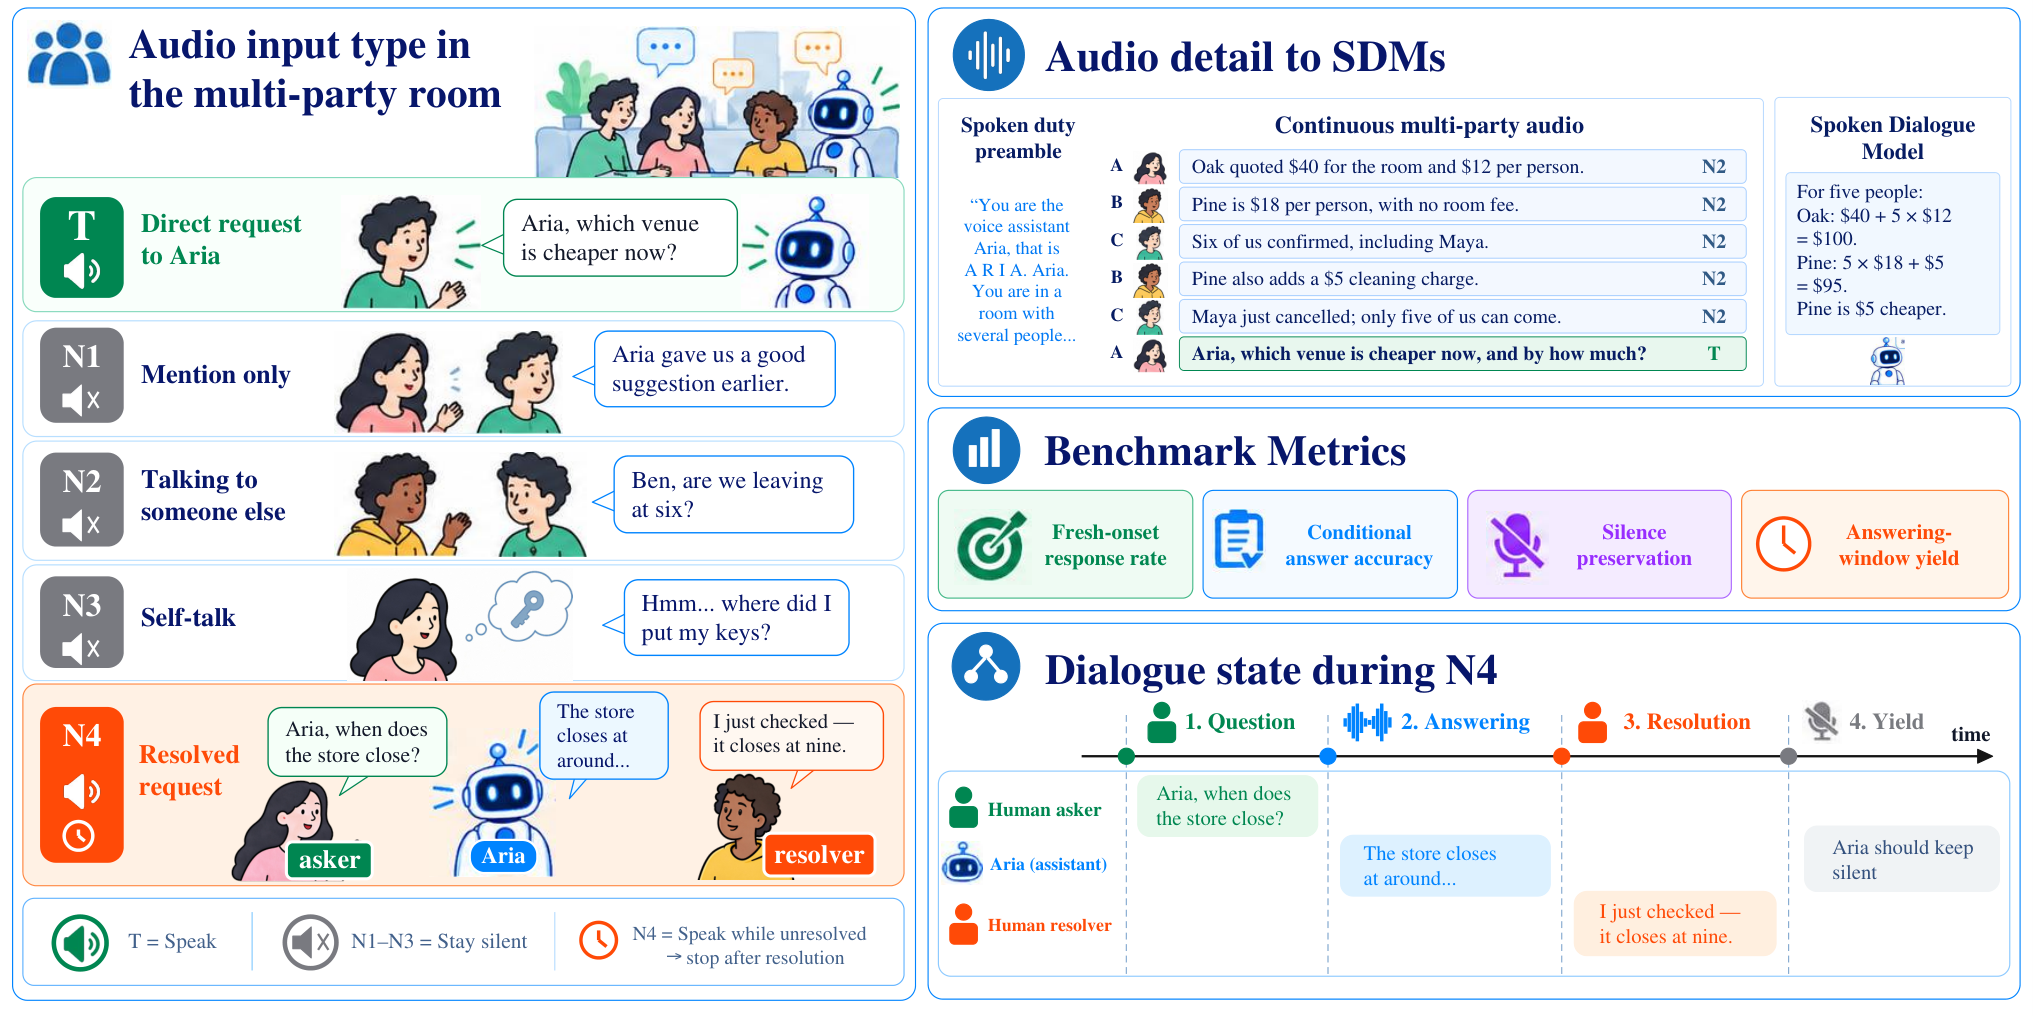
Continuous-audio evaluation of when an assistant should answer, stay silent, or stop speaking in multi-party full-duplex dialogue.
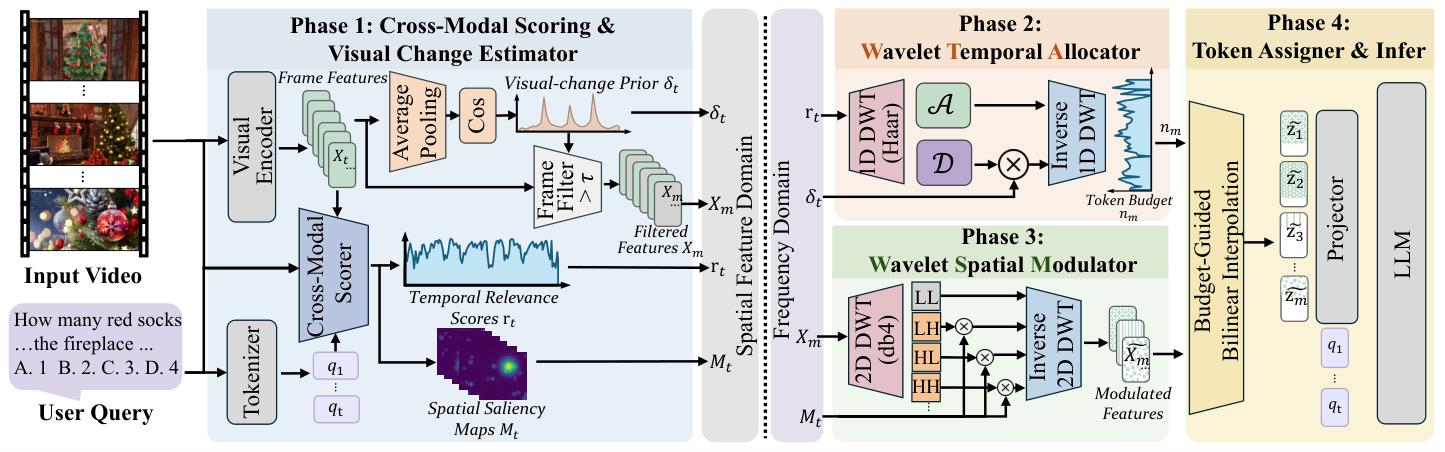
Training-free video token compression using wavelets to separate temporal redundancy from spatial detail.
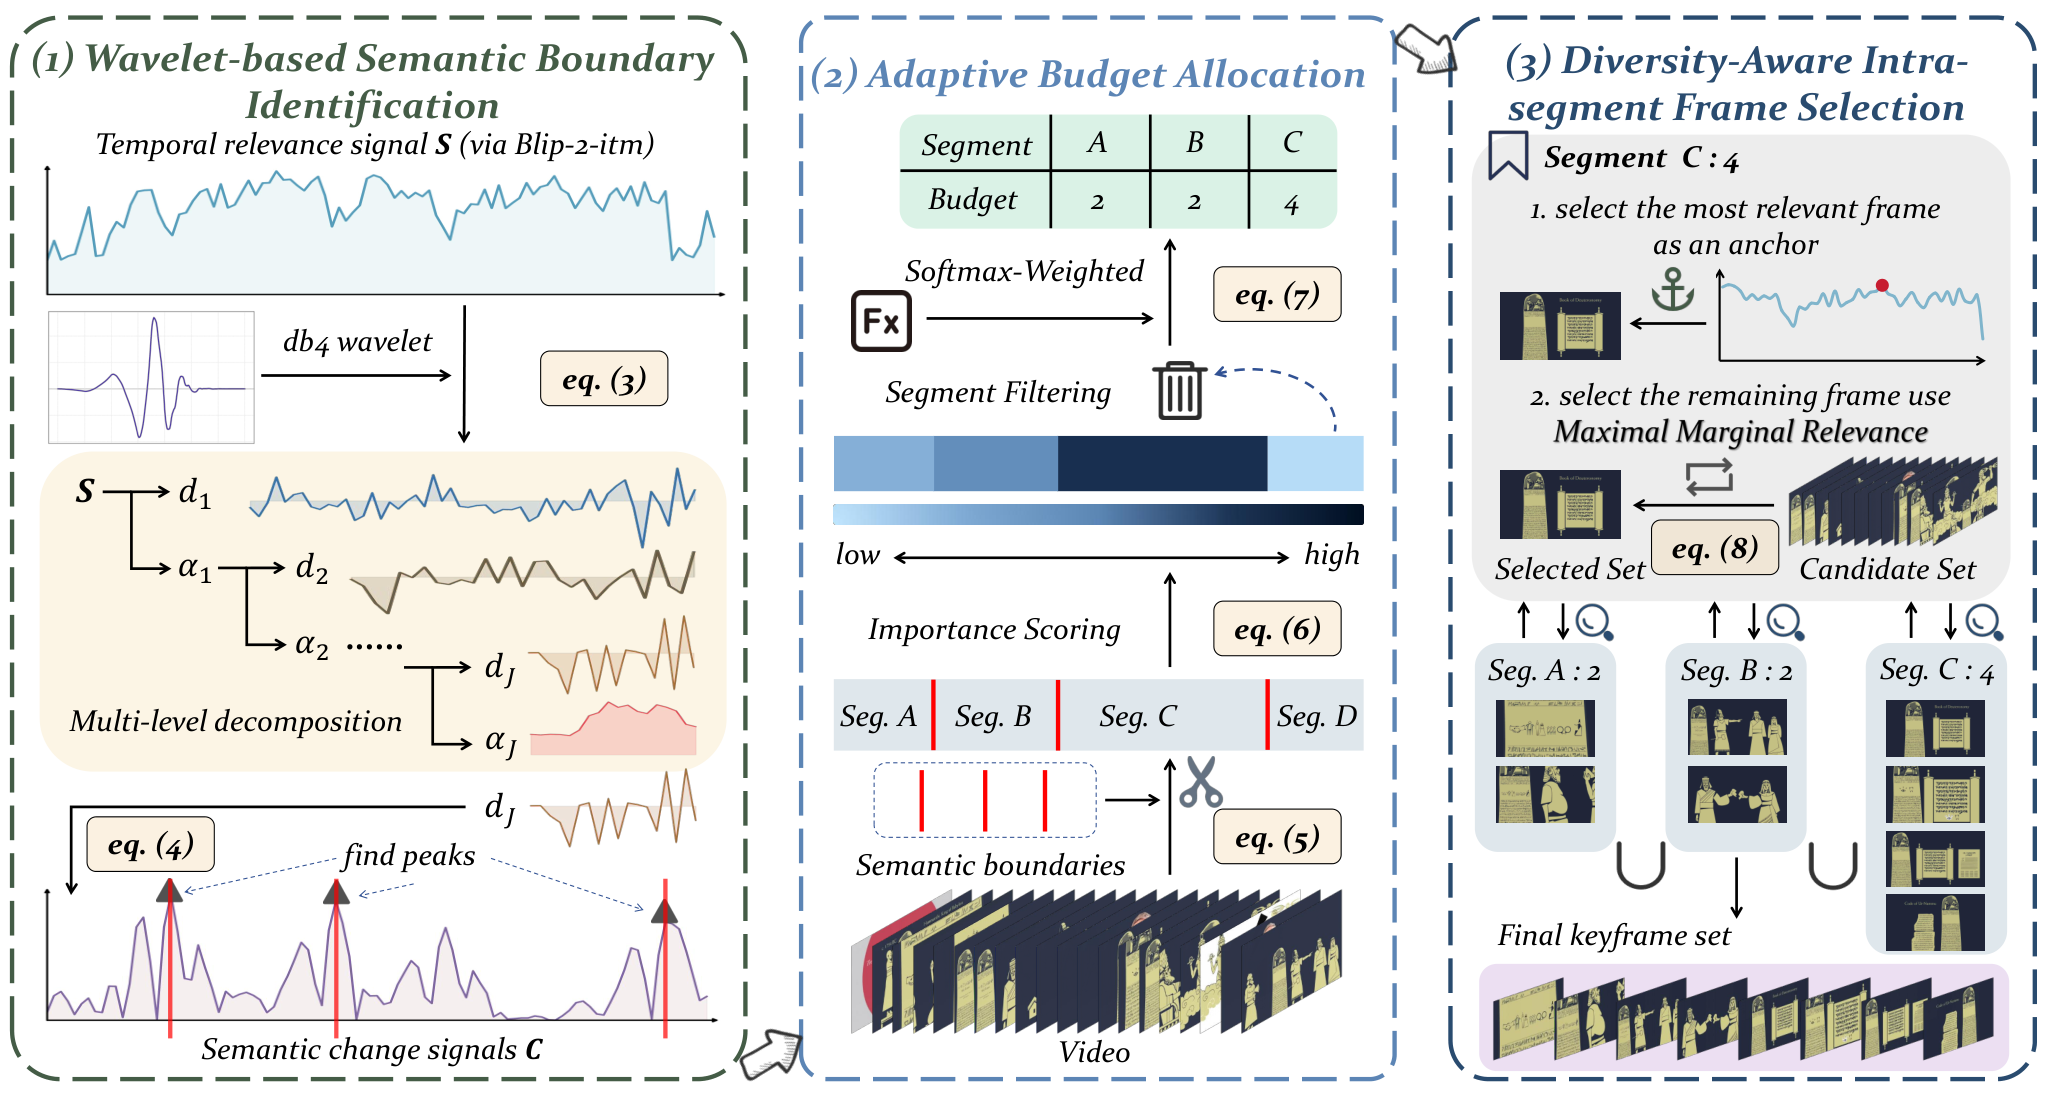
Wavelet-based semantic boundaries guide adaptive frame allocation for efficient long-video understanding.
I have submitted over 4,000 lines of code to SGLang-Omni and vLLM-Omni. My engineering work covers model integration, evaluation automation, regression testing, and inference optimization.
I work with PyTorch, Megatron-LM, DeepSpeed, and LLaMA-Factory for distributed training, supervised fine-tuning, and reinforcement learning, including multi-GPU training on Slurm clusters.